Redact a DOCX before ChatGPT: text, images and export.
To redact a DOCX before ChatGPT, review its text and layout locally, choose placeholders or permanent redaction for accepted findings, inspect embedded images separately, then verify the exported copy.
For HR, legal, recruiting, property and operations professionals working in Word.
Why this workflow matters
Keep the useful context. Remove the unnecessary identity.
Word documents often mix paragraphs, tables, headers, footers and embedded images. The useful privacy workflow is not just a find-and-replace pass: it needs a review surface and a clear warning when image content needs separate OCR or manual inspection.
The goal is a working copy that still makes sense to an AI tool: relationships stay consistent, while accepted names, contacts, addresses and document-specific identifiers become controlled replacements.
A practical sequence
From original file to AI-ready copy.
Four checkpoints
01
Choose the DOCX locally
Open the Word file in the browser workspace. The original file is held for the current session rather than uploaded to the service.
02
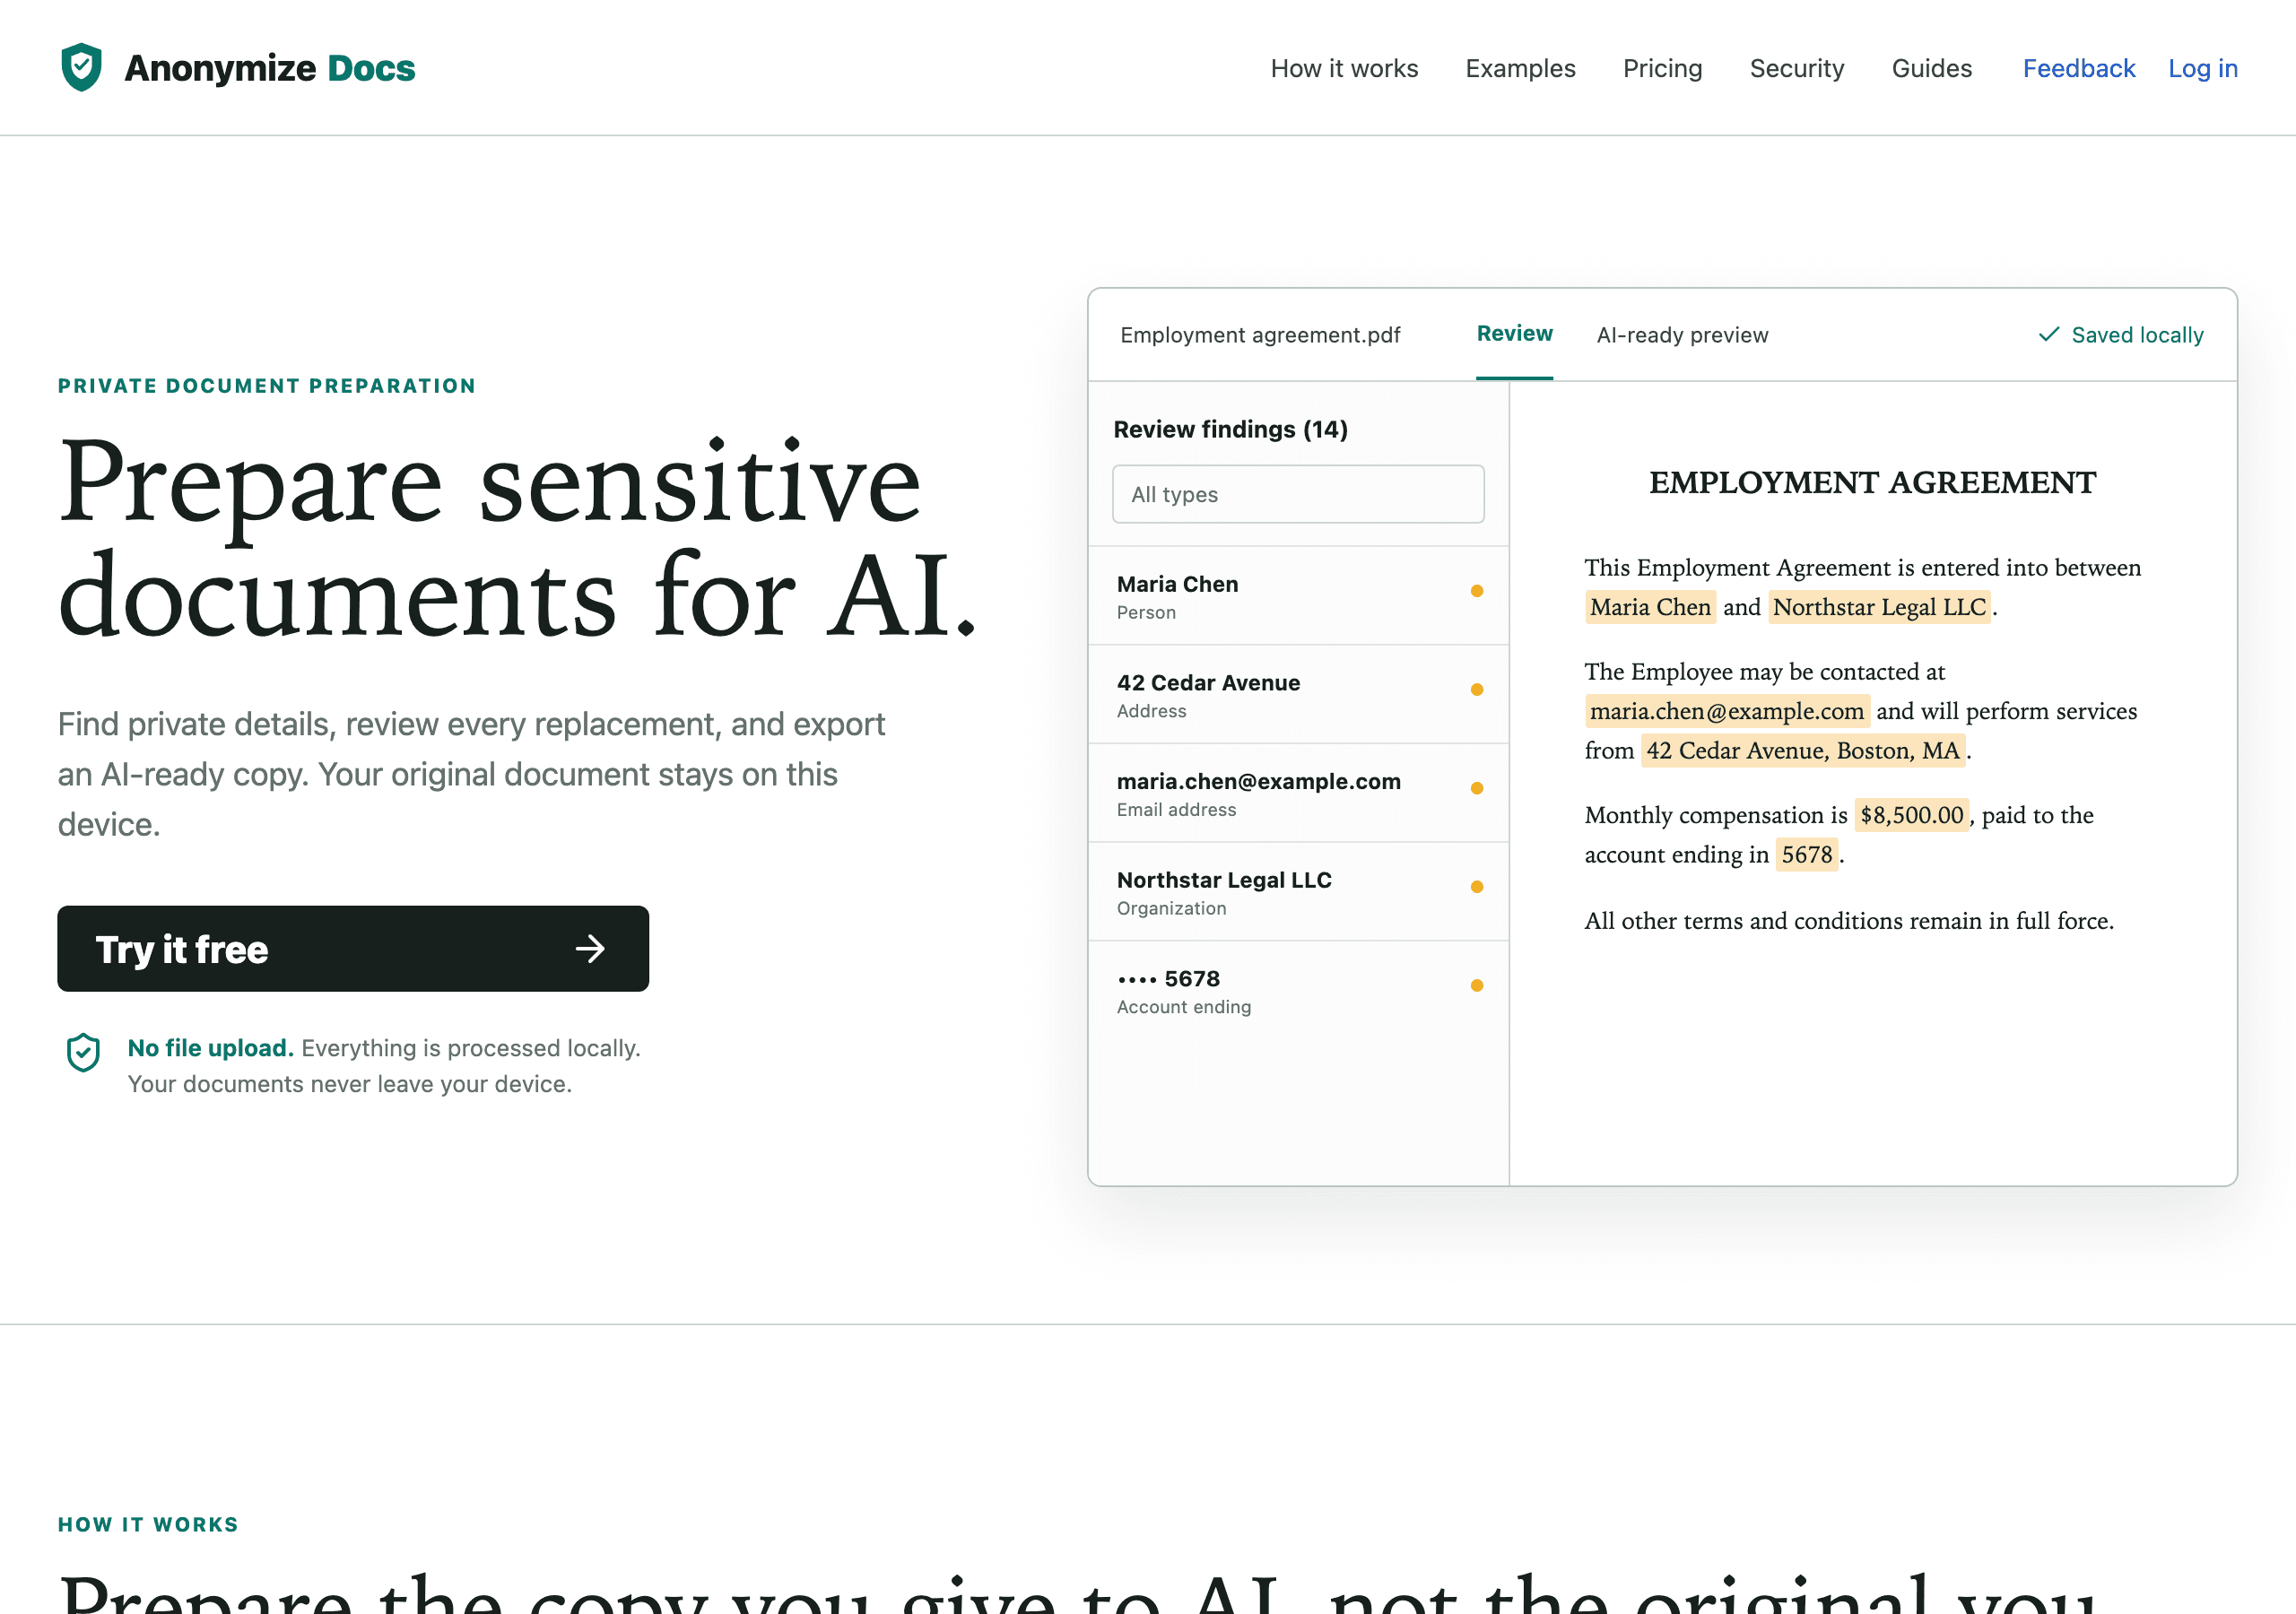
Review text findings
Inspect names, employers, organizations, emails, phone numbers, addresses and unique document identifiers in context.
03
Check non-text content
Embedded screenshots, scanned pages, logos and image-based signatures may need OCR or manual review because they are not ordinary DOCX text.
04
Export and verify
Download the reviewed copy and open it before sharing. Confirm that formatting, tables and image content do not reveal the original values.
Document-specific review
What gets checked before export?
The detector suggests candidates; you decide what changes. For this workflow, start with the fields below and add custom findings when the document contains a unique name, project, matter or identifier.
Paragraphs, tables, headers and footers Candidate, client, employee and counterparty names Employers, companies, brands and locations Emails, phones, addresses and unique identifiers Embedded images, screenshots and scanned pages
Privacy boundary
What stays on your device.
DOCX text is read in the browser for the core workflow.
Original and AI-ready files remain separate until you download the reviewed copy.
OCR coverage is presented as a separate review boundary rather than silently treated as complete.
Human checkpoint
What still needs your judgment.
DOCX export can be sensitive to complex formatting and embedded media. Image OCR coverage and unsupported image formats are separate boundaries. Always open the downloaded document and inspect the output before sharing.
A verified export confirms accepted values were handled. It does not promise that an automated detector found every sensitive detail.
What a useful output looks like
Readable enough for analysis. Safer to share.
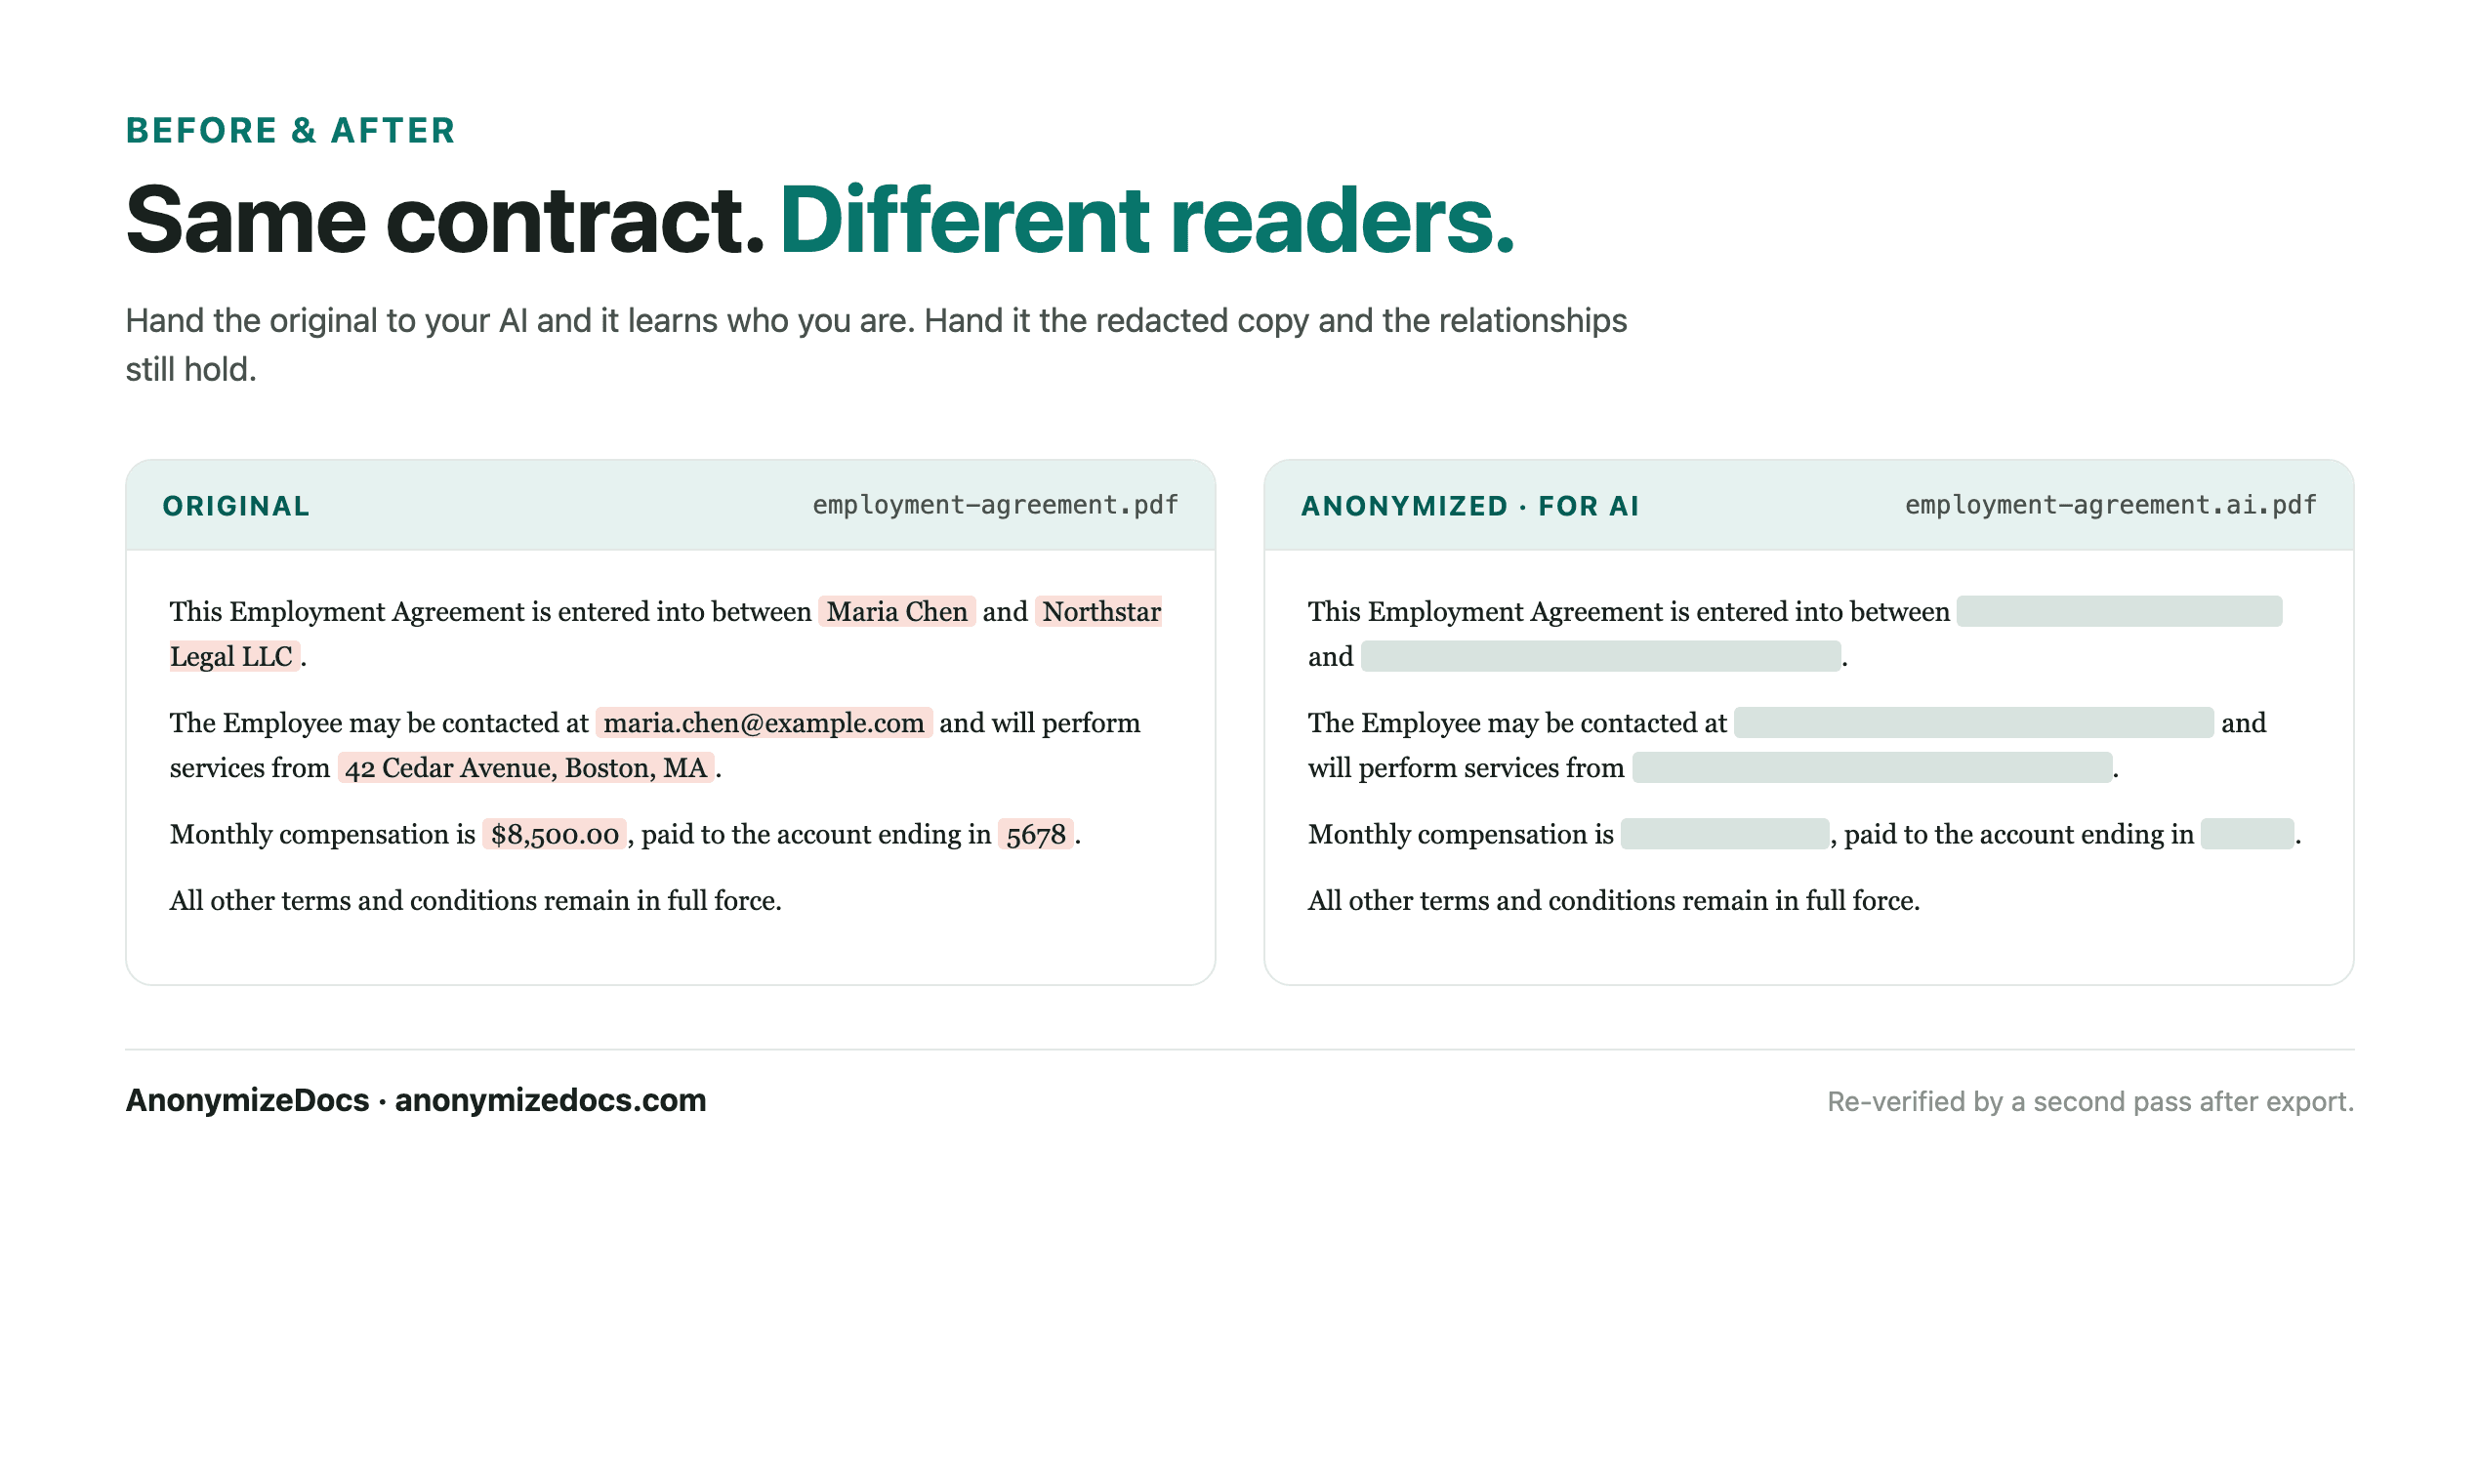
Stable placeholders let the AI distinguish one party from another without receiving the original names. Keep the clauses, dates and relationships the task needs; replace the details that identify the people, companies or matter.
Original identity-bearing valuesReview accept, ignore or editOutput reviewed placeholders or permanent redaction mode
Product evidence
See the review surface before you trust the workflow.
Current UI reference
These are current AnonymizeDocs product visuals, not testimonials or stock illustrations. They show the review, export and privacy boundaries that should be checked on a real file.
Local selection and review checkpoints.Output comparison and the boundary that still needs human verification.
Yes. The text workflow can review and replace likely private values in a DOCX before you upload the new copy to ChatGPT.
Does DOCX redaction also remove names inside images?
Image-based names and screenshots are a separate OCR or manual-review problem. They should not be assumed to be covered by ordinary DOCX text detection.
Will tables and formatting be preserved?
The workflow is designed to preserve useful document structure, but complex Word layouts should always be checked in the exported file before sharing.